
semantica-agi/semantica
Graph-Native Infrastructure for Context and Accountable AI Systems
Build with Backblaze B2
SDKs, agent skills, IDE extensions, and reference pipelines from Backblaze Labs. All open source.
Loading star history...
Use Cases & Benefits
- Provides graph-native infrastructure to build context graphs and knowledge graphs with full decision provenance for accountable AI systems.
- Enables deterministic, explainable, and auditable AI decision intelligence with built-in conflict detection and compliance-ready provenance exports.
- Use for building regulated AI systems that require traceable, queryable decision records and audit trails in finance, healthcare, or legal domains.
- Use for integrating enterprise data platforms like Databricks or Snowflake to convert raw tables into governed, lineage-tracked knowledge graphs without data export.
- Use for data and knowledge engineers needing entity resolution, semantic deduplication, and conflict management across multi-source, messy datasets.
About semantica
Graph-Native Infrastructure for Context and Accountable AI Systems
The Open Source Palantir for AI Agents
Ingest your enterprise data, extract what matters, build a Context Graph and knowledge graph (KG), and run graph analytics and causal reasoning over all of it, with full decision provenance baked in. Explainable, traceable, and trustworthy by design.
Decision Intelligence · Context Management · Deterministic Reasoning · Ontology Management · Knowledge Modeling · End-to-End Traceability
Open Source · Self-Hostable · Auditable · Governed · Zero Vendor Lock-In
Polyglot Graph Storage · RDF & LPG Support · W3C Standards · Interoperable
Built for High-Stakes, Regulated Domains





pip install semantica
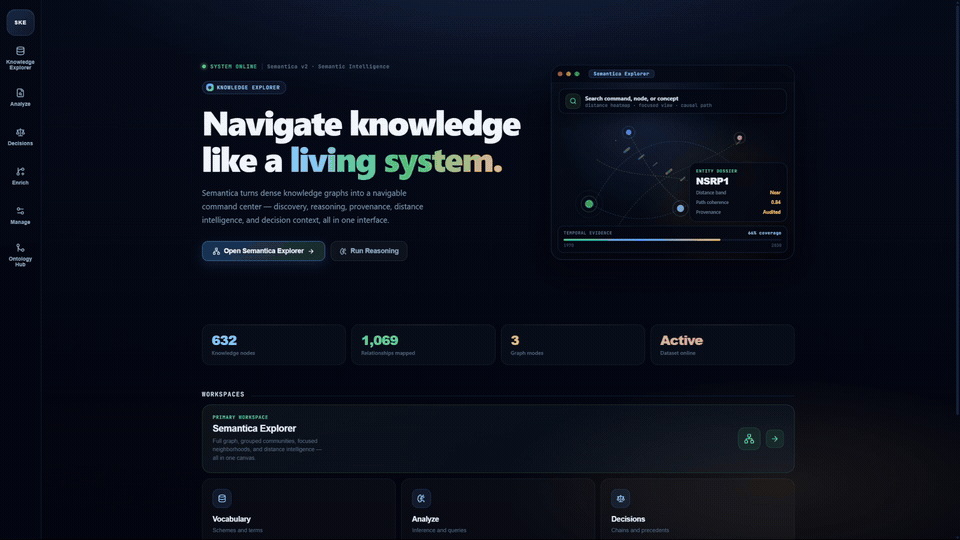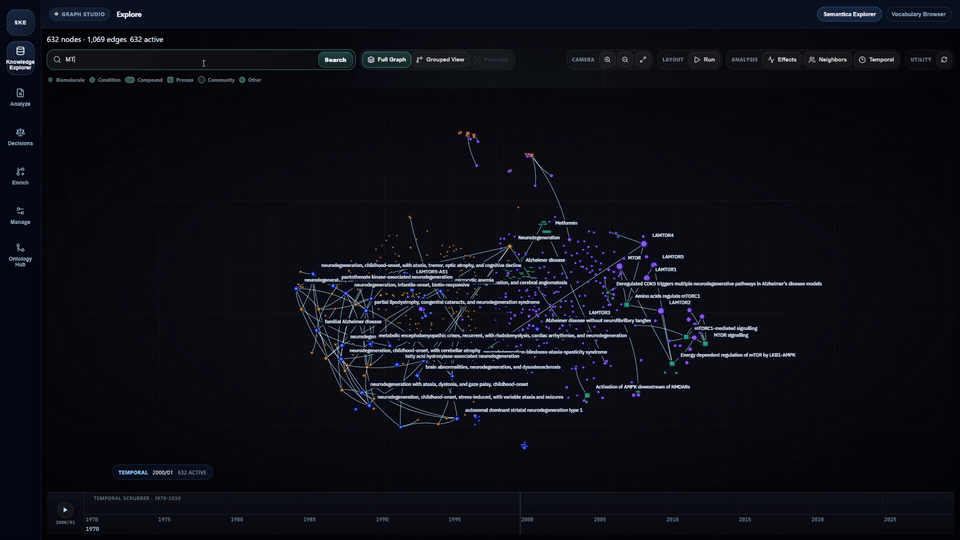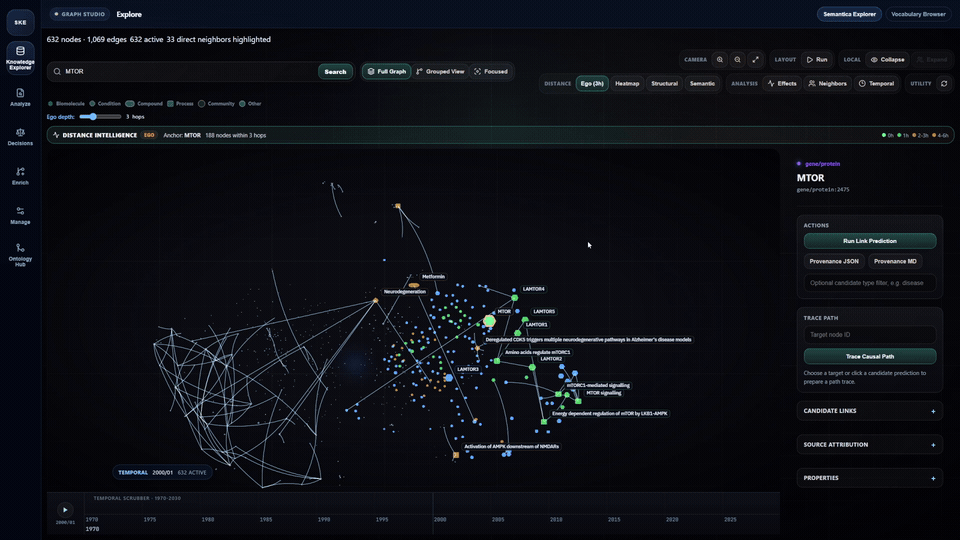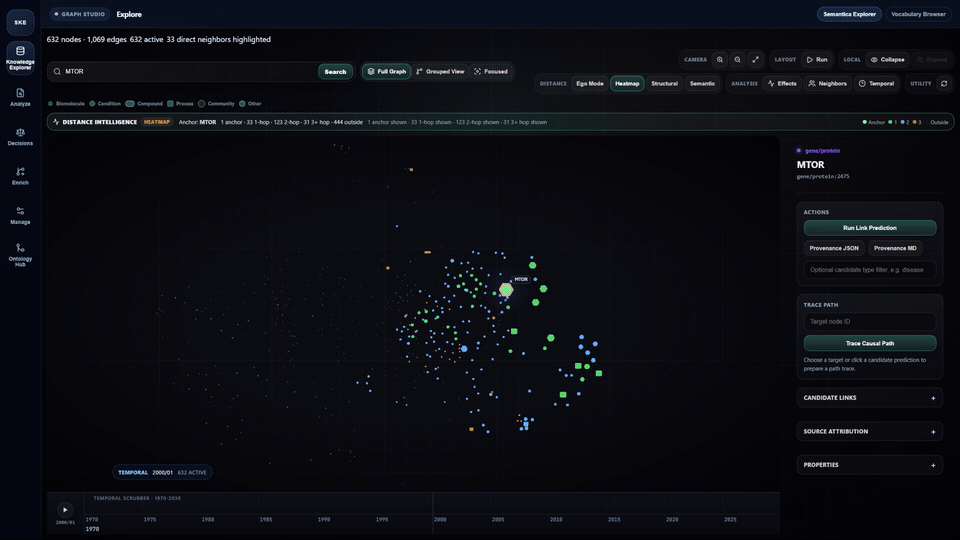
Knowledge Explorer · Context Graphs · Reasoning Engine · Decision Intelligence · Ontology Hub
Most AI agents act without a trail. They store embeddings, not meaning: context that can't be explained, decisions that can't be audited. In lending, that gap is a compliance exposure, not an inconvenience: an underwriting agent's approval has to survive a regulator's "why" months later.
Semantica sits underneath your LLM, vector store, and agent framework as a deterministic infrastructure layer: no LLM required for graph construction, reasoning, or provenance.
Who it's for:
- AI/ML platform teams shipping agents that make consequential decisions and need structured, queryable context built from fragmented raw data, not just a vector index
- Data platform teams on Databricks or Snowflake who need to turn tables already sitting in Unity Catalog or a Snowflake warehouse into a governed, lineage-tracked knowledge graph, without exporting that data to a third-party SaaS first
- Compliance, risk, and audit teams who need a straight answer to "why did the AI do that?" in a format a regulator will actually accept
- Regulated enterprises (finance, healthcare, legal, government, defense) that can't ship a black box, and can't send their data to someone else's SaaS to get one
- Platform and infra engineers who want the KG, reasoning, and provenance stack self-hosted and swappable, not locked to one vendor's backend
- Data and knowledge engineers building a KG from messy, multi-source data: entities and relationships get extracted, conflicting or contradictory facts are flagged instead of silently overwritten, and duplicates are merged before they turn into noise
Quick Start · Architecture · What You Get · Why Semantica · Decision Intelligence · Context Graphs · Recipe: Audit Trail · Module Reference · Integrations · CLI · Performance · Install
What Semantica Gives You
- Context Graphs: A structured, queryable graph of everything your agent knows, decides, and reasons about
- Decision Intelligence: Every decision is a first-class object: traceable, searchable by precedent, and causally linked
- AI Governance & Ontology: SHACL constraints, conflict detection, compliance rules, OWL generation, and SKOS vocabulary management with a visual editor
- Full Auditability: W3C PROV-O provenance on every fact, with audit trails exportable to JSON, CSV, or RDF
- Deterministic Reasoning: Forward chaining, Rete network, Datalog, and SPARQL with fully explainable paths, not black boxes
- Knowledge Pipeline: Multi-source ingestion, entity-aware chunking, NER/relation/event extraction, and knowledge graph construction, with semantic deduplication and provenance-preserving merges throughout
- Enterprise Data Platforms: Native connectors for Databricks (Unity Catalog + Delta Lake, PAT/OAuth M2M auth, catalog/schema/table/lineage introspection) and Snowflake (warehouse/database/schema, key-pair and OAuth auth), so tables already living in your lakehouse or warehouse become graph nodes with provenance, not another export/import hop
- Graph Analytics: Centrality, community detection, link prediction, and shortest-path queries over the graph you just built
- Polyglot Graph Storage: Native RDF (embedded Oxigraph, Blazegraph, Apache Jena, Eclipse RDF4J via SPARQL) and Labeled Property Graphs (Neo4j, FalkorDB, Apache AGE, AWS Neptune via Cypher), plus vector stores, all swappable without touching your code
- Visualization: Explore any graph, ontology, or timeline in an interactive browser workbench
- Drop-in Integrations: Native Agno support, a full-featured MCP server, a comprehensive CLI, a REST API, and plugins across major editors
Why Semantica
| Vector DB + RAG | Plain LLM Memory | Semantica | |
|---|---|---|---|
| Recall method | Embedding similarity | Token window | Graph traversal + semantic search |
| Decision history | Not stored | Not stored | First-class queryable objects |
| Provenance | None | None | W3C PROV-O, source-linked |
| Reasoning | None | Black box | Forward chain, Rete, Datalog, SPARQL |
| Conflict detection | Silent overwrite | Silent overwrite | Detected, flagged, resolved |
| Time travel | No | No | Point-in-time graph snapshots |
| Compliance export | None | None | PROV-O, SHACL, OWL, RDF |
| Policy enforcement | None | None | Built-in rule engine + SHACL |
| Entity resolution | No | No | Blocking + semantic deduplication |
| Multi-agent context | Separate per agent | Separate per agent | Single shared intelligence layer |
Semantica complements your existing stack rather than replacing it. Keep your LLM, vector store, and agent framework exactly as they are; Semantica adds the decision records, causal reasoning, provenance, ontology governance, conflict detection, and audit trails on top. The reasoning engines, KG construction, and provenance layer are fully deterministic; no LLM is required to use them.
Quick Start
pip install semantica
from semantica.context import ContextGraph

graph = ContextGraph(advanced_analytics=True)

# Every agent decision becomes a queryable, auditable knowledge node
decision_id = graph.record_decision(
    category="vendor_selection",
    scenario="Choose cloud provider for HIPAA workload",
    reasoning="AWS offers BAA, mature HIPAA tooling, and existing team expertise",
    outcome="selected_aws",
    confidence=0.93,
)

# Ask "why did this happen?" and get a real, structured answer
chain     = graph.trace_decision_chain(decision_id)       # full causal ancestry
similar   = graph.find_similar_decisions("cloud vendor", max_results=5)  # precedents
impact    = graph.analyze_decision_impact(decision_id)    # downstream influence map
compliant = graph.check_decision_rules({"category": "vendor_selection"})  # policy gate
Verify your install in 5 seconds:
semantica doctor
# Python 3.11.9         pass
# semantica 0.6.0       pass
# faiss vector store    pass
# Config file           pass    ~/.semantica/config.yaml
If Semantica solves a real problem for you, a star helps others find it.
Architecture
Semantica is a real end-to-end pipeline, not a single library with a marketing name. Every stage below is a shipping module, independently importable:
Sources → Ingest → Parse → Normalize → Split → Extract → Conflict Detection → Deduplication
   → Knowledge Graph → [ Ontology · Reasoning · Provenance · Decisions ] → Enriched KG
   → Vector Store + Polyglot Graph Store (RDF & LPG) → Export / Visualize / REST · MCP · CLI
- Ingest: files, web, databases, enterprise data platforms (Databricks, Snowflake), cloud (Google Drive, Elasticsearch), streams (Kafka, Kinesis), Git, email, MCP
- Parse → Normalize → Split: document parsing, text/entity/date normalization, GraphRAG-native entity-aware chunking
- Extract → Conflict Detection → Deduplication: NER, relations, events, triplets; conflicting facts flagged and resolved before they merge
- Knowledge Graph:
GraphBuilderconstructs the graph; bi-temporal facts and full graph analytics (centrality, communities, link prediction) run on top of it - Ontology · Reasoning · Provenance · Decisions: the intelligence layer sitting on the KG, with SHACL/OWL governance, Rete/Datalog/SPARQL inference, W3C PROV-O lineage, and first-class decision records
- Storage: polyglot by design, with RDF triple stores (embedded Oxigraph, Blazegraph, Apache Jena, Eclipse RDF4J), Labeled Property Graphs (Neo4j, FalkorDB, Apache AGE, AWS Neptune), and vector stores, all swappable without touching your code
- Outputs: export (RDF, OWL, Parquet, Cypher, JSON-LD), interactive visualization, and access via REST API, MCP server, or CLI
→ Full Mermaid diagrams for the pipeline and the decision intelligence lifecycle
Decision Intelligence
Decision Intelligence turns every AI choice from an ephemeral inference into a permanent, auditable, queryable record. It answers "what did your AI decide, why, and what happened next?": the question regulators and enterprise risk teams ask with increasing urgency.
In Semantica, a decision is not a log line. It is a first-class graph node with a full lifecycle. In regulated domains, every AI decision must be traceable to a source and defensible to an auditor: record_decision() creates a permanent, structured record exportable as W3C PROV-O, the format most compliance frameworks accept for regulator submission.
record_decision()             → stored as a graph node with full structured context
add_causal_relationship()     → linked to upstream causes and downstream effects
find_similar_decisions()      → semantic precedent search across all past decisions
trace_decision_chain()        → full causal ancestry back to root causes
analyze_decision_impact()     → downstream influence map - everything this decision affected
check_decision_rules()        → policy compliance gate against configurable rule sets
export / audit trail          → W3C PROV-O, CSV, or JSON for regulator submission
from semantica.context import ContextGraph

graph = ContextGraph(advanced_analytics=True)

# Record decisions with full structured context
app_id = graph.record_decision(
    category="credit_application",
    scenario="Personal loan, $85k income, 31% DTI, 3yr employment",
    reasoning="Income meets threshold; employment stable; no adverse credit events",
    outcome="proceed_to_underwriting",
    confidence=0.88,
    metadata={"applicant_id": "A-7291"},
)
uw_id = graph.record_decision(
    category="loan_underwriting",
    scenario="Underwriting review for A-7291",
    reasoning="DTI within policy; clean 36-month credit history",
    outcome="approved",
    confidence=0.94,
)
rate_id = graph.record_decision(
    category="interest_rate",
    scenario="Rate assignment for approved loan A-7291",
    outcome="rate_set_8.9pct",
    reasoning="Prime + 2.4% based on risk tier B2",
    confidence=0.99,
)

# Build the auditable causal chain - relationship_type must be one of
# CAUSED, INFLUENCED, or PRECEDENT_FOR
graph.add_causal_relationship(app_id, uw_id,   relationship_type="CAUSED")
graph.add_causal_relationship(uw_id,  rate_id, relationship_type="INFLUENCED")

# Query the intelligence
chain     = graph.trace_decision_chain(rate_id)
similar   = graph.find_similar_decisions("personal loan approval, 31% DTI", max_results=5)
impact    = graph.analyze_decision_impact(uw_id)
compliant = graph.check_decision_rules({"category": "loan_underwriting", "confidence": 0.94})
insights  = graph.get_decision_insights()
Context Graphs
A Context Graph is the structured memory layer that traditional RAG is missing. Instead of flat embeddings that answer "what is similar?", a Context Graph answers "what is connected, why, and how?" Every entity, relationship, decision, and fact is a first-class node, queryable by graph traversal. Entities link to source documents, decisions link to evidence and consequences, facts carry full provenance, and conflicts are detected, not silently overwritten.
from semantica.context import ContextGraph, AgentContext
from semantica.vector_store import VectorStore

graph = ContextGraph(advanced_analytics=True)

# Add nodes with typed properties
graph.add_node("acme_corp",    "Organization", name="Acme Corp", industry="SaaS")
graph.add_node("alice_chen",   "Person",       name="Alice Chen", role="CTO")
graph.add_node("contract_001", "Contract",     value=2_400_000, currency="USD")

# Add typed, weighted edges (extra kwargs become edge metadata)
graph.add_edge("alice_chen", "acme_corp",    edge_type="works_for",  since="2019-03-01")
graph.add_edge("acme_corp",  "contract_001", edge_type="party_to",   signed="2024-01-15")

# BFS traversal - hop through the graph from any node
neighbors = graph.get_neighbors("acme_corp", hops=2)

# Point-in-time snapshot - the graph as it existed on any past date
snapshot  = graph.state_at("2024-01-01")

# AgentContext - high-level API for agent memory workflows
vs  = VectorStore(backend="faiss")
ctx = AgentContext(vector_store=vs, knowledge_graph=graph)
ctx.store("Alice approved the Acme renewal in Q1 2024", conversation_id="conv_001")
retrieved = ctx.retrieve("who approved the Acme contract?")
Why graph over embeddings: traversal finds connections embeddings miss (a person 3 hops from a contract); every node carries provenance so you can always ask "where did this come from?"; conflicts are flagged before they corrupt your knowledge base; point-in-time snapshots let you replay history without reprocessing.
Recipe: Audit Trail for a Regulated Decision
The flagship pattern: record a causally-linked decision chain, attach provenance to every entity, and export a regulator-ready audit trail.
from semantica.context import ContextGraph
from semantica.provenance import ProvenanceManager
from semantica.export import RDFExporter

graph = ContextGraph(advanced_analytics=True)
prov  = ProvenanceManager(storage_path="./audit.db")

# Record the decision chain
d1 = graph.record_decision(
    category="drug_interaction_check", scenario="Patient P-4821: warfarin + amiodarone co-prescribed",
    reasoning="Amiodarone potentiates warfarin's anticoagulant effect", outcome="flag_for_review", confidence=0.91,
)
d2 = graph.record_decision(
    category="dosage_adjustment", scenario="INR monitoring plan for P-4821",
    reasoning="Reduce warfarin dose per interaction severity; recheck INR in 5 days", outcome="dose_reduced_30pct", confidence=0.87,
)
# relationship_type must be one of CAUSED, INFLUENCED, or PRECEDENT_FOR
graph.add_causal_relationship(d1, d2, relationship_type="CAUSED")

# Track provenance for every entity
prov.track_entity("patient_P4821", source="ehr/medication_orders_2024.json",
                  metadata={"extractor": "NamedEntityRecognizer"})

# Export W3C PROV-O for regulator submission - RDFExporter expects
# {"entities": [...], "relationships": [...]}, so map ContextGraph.to_dict()'s
# {"nodes": [...], "edges": [...]} shape onto it first
graph_dict = graph.to_dict()
kg = {
    "entities": [{"id": n["id"], "type": n["type"], "text": n["content"]} for n in graph_dict["nodes"]],
    "relationships": [
        {"source_id": e["source"], "target_id": e["target"], "type": e["type"]}
        for e in graph_dict["edges"]
    ],
}
RDFExporter().export(kg, "audit_trail.ttl", format="turtle")
More recipes (GraphRAG pipelines, an AML rules engine, ontology-to-KG in one pass) are in More Recipes below.
Explore the Platform
Every module below is independently importable, with working code samples verified against the current source tree; use one or all of them.
| Module | What it does |
|---|---|
semantica.ingest | Files, web, databases, APIs, streams, email, Git, Parquet, Databricks, Snowflake, MCP |
semantica.semantic_extract | NER, relation extraction, event detection, triplet generation |
semantica.kg | Graph construction, centrality, communities, link prediction |
semantica.reasoning | Forward chaining, Rete, Datalog, SPARQL, fully explainable |
semantica.vector_store | FAISS, Qdrant, Weaviate, Milvus, Pinecone, PgVector, hybrid search |
semantica.split | Entity-aware, relation-aware, ontology-aware chunking for GraphRAG |
semantica.provenance | W3C PROV-O lineage on every fact |
semantica.ontology | OWL generation, SHACL validation, SKOS vocabularies |
semantica.conflicts | Detect and resolve conflicting facts across sources |
semantica.deduplication | Entity resolution at scale |
semantica.normalize | Text, entity, date, and number normalization; dataset cleaning |
semantica.pipeline | Declarative, parallel pipeline DSL for ingest → extract → build → export |
semantica.export | RDF, OWL, Parquet, Cypher, JSON-LD |
semantica.visualization | Force-directed graphs, ontology hierarchies, temporal dashboards |
| Temporal Intelligence | Bi-temporal facts, Allen interval algebra, time travel |
| Multi-Agent (Agno) | One shared context graph across every agent on a team |
↓ Expand Module Reference below for every module's working example, or jump to More Recipes, the full Integrations matrix, MCP tool list, and REST endpoints.
Module Reference
Expand any module below for its runnable example.
semantica.ingest: Multi-Source Ingestion
Ingest from files, web, databases, APIs, streams, email, Git repos, Parquet, Databricks, Snowflake, or MCP servers, all through a unified interface.
from semantica.ingest import FileIngestor, WebIngestor, ParquetIngestor, DBIngestor

# Ingest an entire directory of contracts (PDF, DOCX, HTML, TXT)
docs = FileIngestor().ingest_directory("./contracts/", recursive=True)

# Ingest live web content with robots.txt compliance
pages = WebIngestor().ingest_url("https://example.com/reports/annual-2024.html")

# Ingest structured data from Parquet with Snappy compression
records = ParquetIngestor().ingest("./data/transactions.parquet")

# Ingest from a SQL database - specify which tables to pull
rows = DBIngestor().ingest_database(
    connection_string="postgresql://user:pass@localhost/mydb",
    include_tables=["customer_events"],
    max_rows_per_table=50_000,
)
# Enterprise data platforms - pull tables straight out of your lakehouse
# or warehouse, with lineage, instead of exporting to CSV first
from semantica.ingest import DatabricksIngestor, SnowflakeIngestor

# pip install "semantica[db-databricks]"
databricks = DatabricksIngestor(
    host="https://adb-xxx.azuredatabricks.net",
    token="dapi-xxxxxxxx",              # or client_id/client_secret for OAuth M2M
    http_path="/sql/1.0/warehouses/xxxxxxxx",
    catalog="main",
)
customers    = databricks.ingest_table("customers", limit=10_000)
sales        = databricks.ingest_query("SELECT * FROM sales WHERE region = 'EMEA'")
table_lineage = databricks.get_table_lineage("customers", catalog="main", schema="default")  # Unity Catalog lineage

# pip install semantica[db-snowflake]
snowflake = SnowflakeIngestor(
    account="myaccount",
    user="myuser",
    password="mypassword",              # or private_key=... for key-pair; use authenticator="oauth", token=... for OAuth
    warehouse="COMPUTE_WH",
    database="MYDB",
)
orders = snowflake.ingest_table("ORDERS", limit=10_000)
Security Note: Never hardcode credentials (
token,password,private_key) in production code; pass them via environment variables (e.g.,DATABRICKS_TOKEN,SNOWFLAKE_PASSWORD) or a secrets manager.
Supported sources: Local files (PDF, DOCX, PPTX, HTML, TXT, CSV, JSON, YAML, Excel, XML) · Web pages · RSS/Atom feeds · REST APIs · Databases (PostgreSQL, MySQL, SQLite, Oracle, SQL Server) · Parquet datasets · Databricks (Unity Catalog + Delta Lake) · Snowflake · Git repositories · Email (IMAP/POP3) · Message streams (Kafka, RabbitMQ, Kinesis, Pulsar) · MCP resources · Apache Arrow/Feather/IPC (ArrowIngestor)
DuckDB, Elasticsearch, Google Drive, HuggingFace, MongoDB, and Pandas ingestion also ship (DuckDBIngestor, ElasticIngestor, GDriveIngestor, HuggingFaceIngestor, MongoIngestor, PandasIngestor) but aren't re-exported from the top-level semantica.ingest namespace yet — import them directly: from semantica.ingest.duckdb_ingestor import DuckDBIngestor.
semantica.semantic_extract: NER, Relations, Events, Triplets
Extract structured knowledge from raw text in one pass.
from semantica.semantic_extract import (
    NamedEntityRecognizer,
    RelationExtractor,
    EventDetector,
    TripletExtractor,
)

text = """
Anthropic CEO Dario Amodei announced a $7.3B Series E funding round in partnership
with Google and Spark Capital, valuing the company at $61.5B as of Q4 2024.
"""

# Named entity recognition with confidence thresholding
ner = NamedEntityRecognizer(confidence_threshold=0.7)
entities = ner.extract_entities(text)
# → [Entity(name="Dario Amodei", type="PERSON"), Entity(name="Anthropic", type="ORG"),
#    Entity(name="Google", type="ORG"), Entity(name="$7.3B", type="MONEY"), ...]

# Relationship extraction - bidirectional support
rel_extractor = RelationExtractor(confidence_threshold=0.6, bidirectional=True)
relations = rel_extractor.extract_relations(text, entities=entities)
# → [Relation(subject="Dario Amodei", predicate="ceo_of", object="Anthropic"),
#    Relation(subject="Anthropic", predicate="raised", object="$7.3B Series E"), ...]

# Event detection with temporal processing
events = EventDetector(extract_participants=True, extract_time=True).detect_events(text)
# → [Event(type="FUNDING", participants=["Anthropic","Google","Spark Capital"],
#          amount="$7.3B", date="Q4 2024")]

# RDF triplets with optional provenance metadata
triplets = TripletExtractor(include_temporal=True, include_provenance=True).extract_triplets(text)
# → [("Anthropic", "valuation", "$61.5B"), ("Dario Amodei", "is_ceo_of", "Anthropic"), ...]
Batch processing across many documents uses ner.process_batch([...]), not a per-call extract_entities_batch on the facade class.
semantica.kg: Knowledge Graph Construction & Analysis
Build a production knowledge graph from documents and run graph algorithms over it.
from semantica.ingest import FileIngestor
from semantica.kg import (
    GraphBuilder,
    GraphAnalyzer,
    CentralityCalculator,
    CommunityDetector,
    PathFinder,
    LinkPredictor,
    BiTemporalFact,
)
from datetime import datetime

# Build KG - merge duplicate entities, track temporal edges
sources = FileIngestor().ingest_directory("./contracts/", recursive=True)
kg = GraphBuilder(merge_entities=True, enable_temporal=True).build(sources)

# Graph analytics
analyzer    = GraphAnalyzer()
analysis    = analyzer.analyze_graph(kg)             # full graph metrics

centrality  = CentralityCalculator()
degree      = centrality.calculate_degree_centrality(kg)    # most-connected entities
betweenness = centrality.calculate_betweenness_centrality(kg)

communities = CommunityDetector().detect_communities(kg, method="louvain")  # natural clusters
path        = PathFinder().find_shortest_path(kg, "alice_chen", "contract_001")
predictions = LinkPredictor().predict_links(kg, top_k=10)   # relationship predictions

# Bi-temporal facts - track valid time vs. recorded time independently
fact = BiTemporalFact(
    valid_from=datetime(2024, 3, 1),
    valid_until=datetime(2025, 1, 1),
    recorded_at=datetime(2024, 3, 5),
)
semantica.reasoning: Forward Chaining, Rete, Datalog, SPARQL
Run explainable rule-based inference, not a black box.
from semantica.reasoning import ReteEngine, Rule, Fact, RuleType

rete = ReteEngine()
rete.build_network([
    Rule(
        rule_id="aml_flag",
        name="Flag high-risk transactions",
        conditions=[
            {"field": "amount",  "operator": ">",  "value": 10_000},
            {"field": "country", "operator": "in", "value": ["IR", "KP", "SY"]},
        ],
        conclusion="flag_for_compliance_review",
        rule_type=RuleType.IMPLICATION,
    ),
    Rule(
        rule_id="velocity_check",
        name="Flag rapid sequential transfers",
        conditions=[
            {"field": "transfers_in_1h", "operator": ">", "value": 5},
            {"field": "total_amount",    "operator": ">", "value": 50_000},
        ],
        conclusion="flag_velocity_breach",
        rule_type=RuleType.IMPLICATION,
    ),
])

rete.add_fact(Fact("tx_001", "transaction", [{"amount": 15_000, "country": "IR"}]))
flagged = rete.match_patterns()
# → [{"rule": "aml_flag", "matched_facts": ["tx_001"], "conclusion": "flag_for_compliance_review"}]
Current limitation:
ReteEngine's alpha-node condition matcher is intentionally simple in this release — validatematch_patterns()output against your actual rule set before wiring it into a production compliance gate; more selective condition evaluation is on the roadmap.
# Recursive Datalog - natural language for graph queries
from semantica.reasoning import DatalogReasoner

engine = DatalogReasoner()
engine.add_fact("parent(tom, bob)")
engine.add_fact("parent(bob, ann)")
engine.add_fact("parent(ann, pat)")
engine.add_rule("ancestor(X, Y) :- parent(X, Y).")
engine.add_rule("ancestor(X, Z) :- parent(X, Y), ancestor(Y, Z).")
ancestors = engine.query("ancestor(tom, ?X)")
# → [{"X": "bob"}, {"X": "ann"}, {"X": "pat"}]
# Explainable reasoning - trace the path, not just the answer
from semantica.reasoning import ExplanationGenerator, Reasoner

reasoner = Reasoner()
reasoner.add_fact("parent(tom, bob)")
reasoner.add_rule("ancestor(X, Y) :- parent(X, Y)")
result = reasoner.forward_chain()

explainer = ExplanationGenerator()
explanation = explainer.generate_explanation(result)
# → Explanation(conclusion="...", steps=[ReasoningStep(...)], justification=Justification(...))
semantica.vector_store: Hybrid & Filtered Semantic Search
Drop-in vector store with multiple backends, hybrid search, and decision-aware retrieval.
from semantica.vector_store import VectorStore, HybridSearch

# In-memory backend shown here: HybridSearch and explain_decision() work out of the box.
# Swap backend="qdrant" / "weaviate" / "milvus" / "pinecone" / "pgvector" / "faiss" once you
# scale past a single process — search() and store_decision() work identically on all of them.
vs = VectorStore(backend="inmemory", dimension=1536)

# Store a decision with scenario description and outcome
vs.store_decision(
    scenario="Personal loan A-7291, $85k income, 31% DTI, 3yr employment",
    outcome="approved",
    confidence=0.94,
    category="loan_underwriting",
)

# Semantic similarity search
results = vs.search(
    query="personal loan approval with low DTI",
    limit=10,
)

# Hybrid search - dense + sparse retrieval in one pass with RRF fusion
hs   = HybridSearch(vector_store=vs)
hits = hs.search("high-risk transactions 2024")

# Explain why a decision was retrieved
explanation = vs.explain_decision(results[0]["id"])
Backends: faiss · qdrant · weaviate · milvus · pinecone · pgvector · sqlite · inmemory
semantica.split: GraphRAG-Native Document Chunking
KG-aware splitting that preserves entity boundaries, relation triplets, and ontology concepts, essential for GraphRAG pipelines.
from semantica.split import TextSplitter, EntityAwareChunker, RelationAwareChunker

text = open("contracts/master_agreement.txt").read()

# Standard recursive chunking
chunks = TextSplitter(method="recursive", chunk_size=1000, chunk_overlap=200).split(text)

# Entity-aware chunking - never splits a named entity across chunks (GraphRAG)
chunks = TextSplitter(method="entity_aware", ner_method="llm", chunk_size=1000).split(text)

# Relation-aware chunking - preserves (subject, predicate, object) triplets intact
chunks = RelationAwareChunker(chunk_size=1000, preserve_triplets=True).chunk(text)

# Graph-based chunking - uses centrality to find natural community boundaries
chunks = TextSplitter(method="graph_based", chunk_size=1000).split(text)

# Hierarchical chunking - multi-level (section → paragraph → sentence)
chunks = TextSplitter(method="hierarchical", levels=["section", "paragraph"]).split(text)
Supported methods: recursive · token · sentence · paragraph · semantic_transformer · entity_aware · relation_aware · graph_based · ontology_aware · hierarchical · community_detection · centrality_based · llm
semantica.provenance: W3C PROV-O Lineage
Every fact is linked to its source. No black boxes, no mystery outputs.
from semantica.provenance import ProvenanceManager

prov = ProvenanceManager(storage_path="./provenance.db")

# Track where every entity came from
prov.track_entity(
    entity_id="acme_corp",
    source="contracts/acme_master_agreement_2024.pdf",
    metadata={"page": 1, "confidence": 0.97, "extractor": "NamedEntityRecognizer"},
)

# Track a relationship's provenance - entity linkage travels in metadata
prov.track_relationship(
    relationship_id="alice_works_for_acme",
    source="hr_records/employees_q1_2024.csv",
    metadata={"source_entity_id": "alice_chen", "target_entity_id": "acme_corp"},
)

# Answer "where did this come from?"
lineage = prov.get_lineage("acme_corp")
trail   = prov.trace_lineage("alice_chen")   # full ancestor chain
entry   = prov.get_provenance("acme_corp")
semantica.ontology: OWL Generation, SHACL Validation
Generate ontologies from data, validate shapes, and manage your vocabulary.
from semantica.ontology import OntologyGenerator, OntologyValidator

data = {
    "entities": [
        {"id": "acme_corp",  "type": "Organization", "industry": "SaaS", "founded": 2012},
        {"id": "alice_chen", "type": "Person",        "role": "CTO",     "since": 2019},
    ],
    "relationships": [
        {"source": "alice_chen", "target": "acme_corp", "type": "works_for"},
    ],
}

gen       = OntologyGenerator(base_uri="https://semantica.dev/ontology/")
ontology  = gen.generate_ontology(data)
classes   = gen.infer_classes(data)
props     = gen.infer_properties(data, classes)
optimized = gen.optimize_ontology(ontology)

# Validate against SHACL shapes
validator = OntologyValidator()
report    = validator.validate(ontology)
# → ValidationResult(valid=True, consistent=True, satisfiable=True, errors=[], warnings=[])
semantica.conflicts: Conflict Detection & Resolution
Detect and resolve conflicting facts from multiple sources before they corrupt your knowledge base.
from semantica.conflicts import ConflictDetector, ConflictResolver, SourceTracker

entities_from_source_a = [
    {"id": "alice_chen", "role": "CTO",   "salary": 250_000, "start_date": "2019-03-01"},
]
entities_from_source_b = [
    {"id": "alice_chen", "role": "VP Eng", "salary": 275_000, "start_date": "2019-03-01"},
]

# Detect all conflict types: value, type, relationship, temporal, logical
detector   = ConflictDetector()
conflicts  = detector.detect_conflicts(entities_from_source_a + entities_from_source_b)
# → [Conflict(entity="alice_chen", field="role",   values=["CTO","VP Eng"], severity="HIGH"),
#    Conflict(entity="alice_chen", field="salary",  values=[250000,275000],   severity="MEDIUM")]

# Resolve using multiple strategies
resolver = ConflictResolver()
resolved = resolver.resolve_conflicts(conflicts, strategy="credibility_weighted")  # weighted by source trust
resolved = resolver.resolve_conflicts(conflicts, strategy="most_recent")          # prefer most recent
resolved = resolver.resolve_conflicts(conflicts, strategy="voting")               # majority wins

# Track source credibility over time
tracker = SourceTracker()
tracker.register_source("source_a", source_type="document", credibility_score=0.85)
tracker.register_source("source_b", source_type="document", credibility_score=0.72)
semantica.deduplication: Entity Resolution at Scale
Block, cluster, and merge duplicates with semantic similarity.
from semantica.deduplication import DuplicateDetector, EntityMerger

entities = [
    {"id": "e1", "name": "Acme Corporation",  "domain": "acme.com"},
    {"id": "e2", "name": "Acme Corp.",         "domain": "acme.com"},
    {"id": "e3", "name": "ACME Corp",          "domain": "acme.co"},
    {"id": "e4", "name": "Globex Industries",  "domain": "globex.com"},
]

detector   = DuplicateDetector(similarity_threshold=0.75, use_clustering=True)
candidates = detector.detect_duplicates(entities)
groups     = detector.detect_duplicate_groups(entities)
# → DuplicateGroup(entities=["e1","e2","e3"], confidence=0.91, strategy="semantic+blocking")

merger  = EntityMerger(preserve_provenance=True)
ops     = merger.merge_duplicates(entities, strategy="keep_most_complete")
history = merger.get_merge_history()
semantica.normalize: Data Normalization & Cleaning
Standardize text, entities, dates, numbers, and encodings before building your knowledge graph.
from semantica.normalize import (
    TextNormalizer,
    EntityNormalizer,
    DateNormalizer,
    NumberNormalizer,
    DataCleaner,
)

# Unicode, whitespace, casing, HTML tags, smart quotes
text  = TextNormalizer().normalize("  Acme Corp.'s Q4 report...  ")
# → "Acme Corp.'s Q4 report..."

# Alias resolution + entity disambiguation with confidence scores
canonical = EntityNormalizer().normalize_entity("ACME Corp.")
# → NormalizedEntity(canonical="Acme Corporation", type="Organization", confidence=0.91)

# Natural language date parsing with timezone conversion
dt    = DateNormalizer().normalize_date("3 weeks ago")
# → datetime(2026, 7, 1, tzinfo=UTC)

# Unit conversion and currency normalization
price = NumberNormalizer().normalize_number("$1.25M USD")
# → NormalizedNumber(value=1_250_000, currency="USD")

# Deduplicate, validate, and impute missing values across a dataset
clean = DataCleaner().clean_data(records, remove_duplicates=True, handle_missing=True)
semantica.pipeline: Pipeline DSL
Compose ingestion, extraction, and graph-building into a declarative, parallel pipeline.
from semantica.pipeline import PipelineBuilder, ExecutionEngine

builder = PipelineBuilder()

# add_step() returns the created PipelineStep, not the builder, so these don't chain
builder.add_step("ingest",      step_type="ingest",           source="./contracts/", recursive=True)
builder.add_step("extract",     step_type="ner_extract")
builder.add_step("relations",   step_type="relation_extract")
builder.add_step("build_kg",    step_type="kg_build",         merge_entities=True)
builder.add_step("deduplicate", step_type="deduplicate",      threshold=0.75)
builder.add_step("export",      step_type="export",           format="turtle", output="kg.ttl")

# connect_steps() and set_parallelism() return the builder, so these do chain
pipeline = (
    builder
    .connect_steps("ingest",      "extract")
    .connect_steps("extract",     "relations")
    .connect_steps("relations",   "build_kg")
    .connect_steps("build_kg",    "deduplicate")
    .connect_steps("deduplicate", "export")
    .set_parallelism(4)
    .build(name="contracts_pipeline")
)

engine   = ExecutionEngine()
result   = engine.execute_pipeline(pipeline)
status   = engine.get_pipeline_status(pipeline.name)
progress = engine.get_progress(pipeline.name)
Temporal Intelligence: Bi-Temporal Graphs & Time Travel
Track when facts were true in the world vs. when they were recorded, and query either axis.
from semantica.context import ContextGraph
from semantica.kg import (
    BiTemporalFact,
    TemporalGraphQuery,
    TemporalNormalizer,
)
from datetime import datetime

graph = ContextGraph(advanced_analytics=True)
graph.add_node("alice_chen", "Person",       role="VP Engineering")
graph.add_node("acme_corp",  "Organization", valuation=1_200_000_000)

# A temporally-bounded edge - valid_from/valid_until define when it held true
graph.add_edge(
    "alice_chen", "acme_corp", edge_type="works_for",
    valid_from="2024-03-01T00:00:00", valid_until="2025-01-01T00:00:00",
)

# Point-in-time snapshots - replay history without reprocessing
snapshot_2023 = graph.state_at("2023-06-01")
snapshot_2024 = graph.state_at("2024-01-01")

# Bi-temporal facts - valid_time is when true in the world;
# recorded_at is when you learned about it
fact = BiTemporalFact(
    valid_from=datetime(2024, 3, 1),
    valid_until=datetime(2025, 1, 1),
    recorded_at=datetime(2024, 3, 5),
)

# Query facts valid within a time window - query_time_range() expects
# {"relationships": [...]} with source_id/target_id keys, which differs from
# ContextGraph.to_dict()'s {"nodes", "edges"} shape, so map it first
graph_dict = graph.to_dict()
kg_relationships = {
    "relationships": [
        {**e, "source_id": e["source"], "target_id": e["target"]}
        for e in graph_dict["edges"]
    ]
}

tq = TemporalGraphQuery()
facts_in_window = tq.query_time_range(
    kg_relationships, query="valid_facts", start_time="2024-01-01", end_time="2024-12-31"
)

# Normalize natural language temporal expressions - returns a (start, end) range
norm = TemporalNormalizer()
start, end = norm.normalize("last quarter")
semantica.export: RDF, OWL, Parquet, Cypher, JSON-LD
Export to any format required by regulators, graph databases, or downstream systems.
from semantica.export import (
    RDFExporter,
    JSONExporter,
    ParquetExporter,
    LPGExporter,
    ReportGenerator,
)

kg = {"entities": [...], "relationships": [...]}

rdf = RDFExporter()
turtle_str = rdf.export_to_rdf(kg, format="turtle")     # returns string
jsonld_str = rdf.export_to_rdf(kg, format="json-ld")

rdf.export(kg, "kg_audit.ttl",    format="turtle")
rdf.export(kg, "kg_audit.jsonld", format="json-ld")
rdf.export(kg, "kg_audit.nt",     format="n-triples")

# Columnar analytics - Snappy-compressed Parquet (writes kg_snapshot_entities.parquet
# and kg_snapshot_relationships.parquet)
ParquetExporter(compression="snappy").export_knowledge_graph(kg, "kg_snapshot")

# JSON knowledge graph
JSONExporter().export_knowledge_graph(kg, "kg.json")

# Neo4j / Memgraph Cypher statements for graph database import
LPGExporter().export(kg, "kg_import.cypher")

# Human-readable HTML report
ReportGenerator().generate_report(
    {"title": "KG Audit Report", "summary": "Weekly ingestion summary", "metrics": {"entities": len(kg["entities"])}},
    file_path="audit_report.html",
    format="html",
)
semantica.visualization: Interactive Graph Workbench
Render force-directed graphs, community maps, ontology hierarchies, and temporal dashboards.
from semantica.visualization import (
    KGVisualizer,
    OntologyVisualizer,
    EmbeddingVisualizer,
    TemporalVisualizer,
)
import numpy as np

kg = {"entities": [...], "relationships": [...]}

# Interactive force-directed graph (opens in browser)
viz = KGVisualizer(layout="force", color_scheme="default")
viz.visualize_network(kg, output="interactive", file_path="kg.html")
viz.visualize_communities(kg, communities, output="interactive")
viz.visualize_centrality(kg, centrality, centrality_type="degree")
viz.visualize_entity_types(kg, output="html", file_path="entity_types.html")

# Ontology class hierarchy
OntologyVisualizer().visualize_hierarchy(ontology, output="interactive")

# 2D embedding projection (UMAP / t-SNE / PCA)
EmbeddingVisualizer().visualize_2d_projection(
    embeddings=np.array([...]),
    labels=["entity_a", "entity_b"],
    method="umap",
)

# Timeline scrubber - watch the graph evolve
TemporalVisualizer().visualize_timeline(kg, output="interactive")
Multi-Agent Shared Context with Agno
One shared intelligence layer. All agents read and write to the same context graph.
# pip install semantica[agno]
from agno.agent import Agent
from agno.team import Team
from agno.models.anthropic import Claude
from semantica.context import ContextGraph
from semantica.vector_store import VectorStore
from integrations.agno import AgnoSharedContext, AgnoDecisionKit, AgnoKGToolkit

shared = AgnoSharedContext(
    vector_store=VectorStore(backend="faiss"),
    knowledge_graph=ContextGraph(advanced_analytics=True),
    decision_tracking=True,
)

researcher = Agent(
    name="Researcher",
    model=Claude(id="claude-sonnet-4-5"),
    memory=shared.bind_agent("researcher"),
    tools=[AgnoKGToolkit(context=shared)],
)
analyst = Agent(
    name="Analyst",
    model=Claude(id="claude-sonnet-4-5"),
    memory=shared.bind_agent("analyst"),
    tools=[AgnoDecisionKit(context=shared)],
)

team = Team(agents=[researcher, analyst], mode="coordinate")
# Researcher's findings are instantly available to the Analyst - no copy, no sync
→ runnable notebooks in the cookbook, each self-contained and runnable in under 5 minutes
More Recipes
The flagship audit-trail recipe is above. Here are three more common patterns.
End-to-End GraphRAG Pipeline
from semantica.ingest import FileIngestor
from semantica.split import TextSplitter
from semantica.semantic_extract import NamedEntityRecognizer, RelationExtractor
from semantica.kg import GraphBuilder
from semantica.vector_store import VectorStore, HybridSearch
from semantica.context import AgentContext

# 1. Ingest
docs = FileIngestor().ingest_directory("./docs/", recursive=True)

# 2. Entity-aware chunking - never splits an entity across a chunk boundary
splitter = TextSplitter(method="entity_aware", chunk_size=1000)
chunks   = [splitter.split(doc["text"]) for doc in docs]

# 3. Extract entities and relations
ner      = NamedEntityRecognizer(confidence_threshold=0.7)
rel_ext  = RelationExtractor(confidence_threshold=0.6)
entities = [ner.extract_entities(chunk) for chunk_group in chunks for chunk in chunk_group]

# 4. Build KG
kg = GraphBuilder(merge_entities=True, enable_temporal=True).build(docs)

# 5. Hybrid retrieval
vs  = VectorStore(backend="inmemory")
ctx = AgentContext(vector_store=vs, knowledge_graph=kg)
ctx.store("Alice approved the Acme renewal in Q1 2024", conversation_id="c1")

results = HybridSearch(vector_store=vs).search("who approved the renewal?")
AML Rules Engine
from semantica.reasoning import ReteEngine, Rule, Fact, RuleType

rete = ReteEngine()
rete.build_network([
    Rule(
        rule_id="sanctions_check",
        name="Flag sanctioned-country transactions",
        conditions=[
            {"field": "amount",  "operator": ">",  "value": 10_000},
            {"field": "country", "operator": "in", "value": ["IR", "KP", "SY", "CU"]},
        ],
        conclusion="flag_for_compliance_review",
        rule_type=RuleType.IMPLICATION,
    ),
])

# Run the rule across a batch of incoming transactions, not just one
for tx in [
    Fact("tx_101", "transaction", [{"amount": 25_000, "country": "IR"}]),
    Fact("tx_102", "transaction", [{"amount": 4_500,  "country": "DE"}]),
    Fact("tx_103", "transaction", [{"amount": 60_000, "country": "KP"}]),
]:
    rete.add_fact(tx)

flagged = rete.match_patterns()
Same condition-matcher caveat as above applies — validate against your rule set before production use.
Ontology-to-Knowledge-Graph in One Pass
from semantica.ingest import FileIngestor
from semantica.semantic_extract import NamedEntityRecognizer, RelationExtractor
from semantica.kg import GraphBuilder
from semantica.ontology import OntologyGenerator, OntologyValidator
from semantica.export import RDFExporter

sources   = FileIngestor().ingest_directory("./contracts/")
ner       = NamedEntityRecognizer(confidence_threshold=0.7)
entities  = ner.process_batch([s["text"] for s in sources])

kg  = GraphBuilder(merge_entities=True).build(sources)
gen = OntologyGenerator(base_uri="https://myco.dev/ontology/")
ont = gen.generate_ontology({"entities": entities[0], "relationships": []})

report = OntologyValidator().validate(ont)
if report.valid:
    RDFExporter().export({"entities": entities[0]}, "ontology.ttl", format="turtle")
Features at a Glance
| Capability | Highlights |
|---|---|
| Context Graphs | Queryable graph of entities, decisions, relationships; causal links; cross-graph navigation |
| Decision Intelligence | record_decision · trace_decision_chain · find_similar_decisions · analyze_decision_impact · check_decision_rules |
| Temporal Intelligence | Point-in-time snapshots · Allen interval algebra (13 relations) · TemporalNormalizer · bi-temporal provenance |
| Distance Intelligence | N×N semantic distance matrices · ego-mode visualization · distance bands · embedding cache |
| Semantic Extraction | NER · relation extraction · event detection · triplet generation · coreference |
| Reasoning Engines | Forward chaining · Rete · deductive · abductive · SPARQL · Datalog with explainable output |
| GraphRAG Chunking | Entity-aware · relation-aware · graph-based · ontology-aware · community-detection chunking |
| Conflict Detection | Value / type / relationship / temporal / logical conflicts · multiple resolution strategies |
| Provenance | W3C PROV-O · every fact traced to source · audit log export JSON/CSV/RDF |
| Ontology Hub | SHACL Studio · visual editor · cross-ontology alignments · health dashboard |
| Vector Store | FAISS · Pinecone · Weaviate · Qdrant · Milvus · PgVector · hybrid + filtered search |
| Graph Databases (LPG) | Neo4j · FalkorDB · Apache AGE · AWS Neptune |
| Triple Stores (RDF) | Oxigraph (embedded) · Blazegraph · Apache Jena · Eclipse RDF4J · unified TripletStore interface · SPARQL query & bulk load |
| Enterprise Data Platforms | Databricks (DatabricksIngestor: Unity Catalog + Delta Lake, PAT/OAuth M2M, table/query ingestion, catalog/schema/table/lineage introspection) · Snowflake (SnowflakeIngestor: warehouse/database/schema, password/key-pair/OAuth auth) |
| LLM Providers | All already supported today: OpenAI (GPT-4o, o1, o3) · Anthropic (Claude) · Google Gemini · Mistral · Meta Llama · Groq · Cohere · Azure OpenAI · AWS Bedrock · Ollama · DeepSeek · Perplexity · Together AI · Fireworks AI · Replicate · HuggingFace · via semantica.llms and LiteLLM |
Performance
Benchmarks from v0.5.0 on a 118,000-node production graph:
| Operation | Before | After | Improvement |
|---|---|---|---|
| Node search (118k nodes) | 24 ms | 0.004 ms | 6,000× faster |
| Embedding cache hit | cold load | revision-based cache | 10× throughput |
| Semantic deduplication | baseline | optimized candidate gen | 6.98× faster |
| Candidate generation | baseline | blocking strategy | 63.6% faster |
Measured on a 118,000-node production graph (AMD EPYC, 64 GB RAM); the deduplication/candidate-generation figures are historical measurements recorded in CHANGELOG.md rather than an automated tests/ assertion. Results vary by hardware, dataset topology, and backend selection — run pytest tests/vector_store/test_performance_benchmarks.py -s to measure your own data.
CLI
Every capability is available from the terminal. The CLI ships with the package, no separate install required.
pip install semantica
semantica        # startup dashboard
semantica doctor # health check
semantica --help # full grouped command reference
Start with semantica, verify with doctor, build a graph, and explore the command groups from one terminal.
Command groups: ingest · parse · extract · kg · reason · decision · temporal · provenance · ontology · embed · deduplicate · validate · export · visualize · pipeline · server · explorer · mcp · doctor · shell · init · watch
Integrations
Native plugin bundles for Claude Code, Cursor, Codex, Windsurf, Cline, Continue, VS Code, and OpenClaw; a full-featured MCP server for any MCP-compatible client; a comprehensive REST API; and first-class Agno support for multi-agent shared context. Every major LLM provider is already supported via semantica.llms and LiteLLM: OpenAI, Anthropic, Gemini, Mistral, Llama, Groq, Cohere, Azure, Bedrock, Ollama, DeepSeek, HuggingFace, and more.
MCP setup takes 30 seconds — see MCP Server below.
Full integrations matrix (editors, MCP clients, REST clients, agentic frameworks)
| Native Plugin Bundle | MCP Server + Plugin | ||||||
|---|---|---|---|---|---|---|---|
 Claude Code Skills · agents · hooks |
 Cursor Skills · agents |
 Codex CLI Skills · agents |
 Windsurf plugin |
 Cline plugin |
 Continue plugin |
 VS Code plugin |
 OpenClaw MCP + plugin |
| MCP Server | REST API | ||||||
|
Claude Desktop MCP server |
 GitHub Copilot REST API |
 Roo Code REST API |
 Goose REST API |
 Kilo Code REST API |
 Aider REST API |
 Amazon Q REST API |
 Zed REST API |
Agentic Frameworks
| Native Integration | |||||||
|---|---|---|---|---|---|---|---|
 Agno First-class · pip install semantica[agno]
| |||||||
| Already Supported via REST API & MCP | |||||||
 LangChain REST API · MCP |
LangGraph REST API · MCP |
 CrewAI REST API · MCP |
 LlamaIndex REST API · MCP |
AutoGen REST API · MCP |
OpenAI Agents REST API · MCP |
 Google ADK REST API · MCP | |
| Native SDK Integration (Coming Soon) | |||||||
|
LangChain Dedicated toolkit |
CrewAI Dedicated toolkit |
LlamaIndex Dedicated toolkit |
AutoGen Dedicated toolkit |
OpenAI Agents Dedicated toolkit |
Google ADK Dedicated toolkit | ||
MCP Server
Connect any MCP-compatible client (Claude Desktop, Windsurf, Cline, VS Code) in 30 seconds:
python -m semantica.mcp_server
# or via the installed entry point
semantica-mcp
{
  "mcpServers": {
    "semantica": { "command": "python", "args": ["-m", "semantica.mcp_server"] }
  }
}
Tools exposed over MCP:
| Tool | What it does |
|---|---|
extract_entities | NER on any text |
extract_relations | Relation extraction |
record_decision | Persist a decision node |
query_decisions | Search decision history |
find_precedents | Semantic precedent lookup |
get_causal_chain | Full causal ancestry |
add_entity | Add a KG node |
add_relationship | Add a KG edge |
run_reasoning | Execute rule set |
get_graph_analytics | Centrality, communities |
export_graph | Export to RDF/JSON/Parquet |
get_graph_summary | Graph statistics |
REST API
# Start the backend
python -m semantica.server   # port 8000

# Extract entities & relations via REST
curl -X POST http://localhost:8000/api/enrich/extract \
  -H "Content-Type: application/json" \
  -d '{"text": "Apple CEO Tim Cook announced record earnings."}'

# List recorded decisions
curl "http://localhost:8000/api/decisions?category=vendor_selection"

# Query the knowledge graph
curl "http://localhost:8000/api/graph/node/acme_corp/neighbors?depth=2"
REST endpoints span: enrich (extract) · graph · decisions · reasoning · provenance · ontology · embeddings · search · export · pipeline · temporal · deduplication
Plugin Bundles
Domain skills: extract · ingest · query · ontology · validate · deduplicate · embed · reason · decision · causal · temporal · provenance · policy · explain · export · change · visualize
Specialized agents: kg-assistant · decision-advisor · explainability
Bundles for Claude Code, Cursor, Codex, Windsurf, Cline, Continue, VS Code, and OpenClaw in plugins/.
Knowledge Explorer
A browser-based graph workbench. Pan and zoom live graphs, scrub the timeline, review every decision's causal chain, resolve duplicates, and author your ontology visually. Built on React 19 + Sigma.js.
| Workspace | What you can do |
|---|---|
| Knowledge Graph | Live Sigma.js canvas with ForceAtlas2 layout, Ego Mode, semantic distance heatmap |
| Timeline | Scrub through temporal events and watch the graph evolve |
| Decisions | Browse the causal chain behind every recorded decision |
| Registry | Live audit log of every graph mutation |
| Entity Resolution | Review and merge duplicates |
| Ontology Hub | SHACL Studio, visual editor, cross-ontology alignments, SKOS browser |
| Lineage | W3C PROV-O provenance visualization for any entity |
Quickest way to start (no Node.js required):
pip install "semantica[explorer]"
semantica-explorer --graph my_graph.json
# Dashboard opens at http://127.0.0.1:8000
For contributor / dev-server setup: explorer/README.md: Local Setup Guide
What's New in v0.6.0
- Named-Graph Support for
JenaStore: Migrated ontordflib.Dataset(default_union=False), completing cross-backend named-graph parity across Blazegraph, RDF4J, and Jena;add_triplets()gains agraph=option - SPARQL CONSTRUCT Query Templates: Parameterized, injection-safe
CONSTRUCTtemplates extended from Blazegraph-only to RDF4J and Jena, plus pipeline integration via theconstruct_templatestep type - Databricks Connector:
DatabricksIngestorfor Unity Catalog + Delta Lake ingestion, with PAT/OAuth M2M auth, table/query ingestion, and catalog/schema/table/lineage introspection. Install withpip install "semantica[db-databricks]" - SQLite Vector Store Backend:
SQLiteVecStore, a disk-backed local vector store onsqlite-vec'svec0virtual tables, with Cosine/L2 metrics, metadata filtering, and WAL mode. Install withpip install semantica[vectorstore-sqlite]
→ Full release notes · Changelog
Built for High-Stakes Domains
Semantica is designed for environments where AI outputs must be explainable, auditable, and defensible, and where the data itself can't leave your infrastructure. Self-hostable with zero vendor lock-in, it's built as much for organizations handling confidential or classified data as for regulated industries chasing an audit trail:
- Finance: Loan underwriting audit trails, fraud detection, AML compliance, regulatory risk knowledge graphs
- Healthcare: Clinical decision support, drug interaction graphs, and patient safety audit trails
- Legal: Evidence-backed research, contract analysis, case law reasoning, and privilege tracking
- Government & Defense: Policy decision records, classified information governance, and regulatory reporting, fully self-hosted with no data leaving your perimeter
- Law Enforcement: Case linkage, evidence provenance chains, and investigative knowledge graphs that hold up under legal scrutiny
- Cybersecurity: Threat attribution, incident response timelines, and IOC provenance tracking
- Autonomous Systems: Decision logs, safety validation, and explainable AI for certification
Installation
pip install semantica           # core
pip install semantica[all]      # everything
pip install semantica[agno]                 # Agno multi-agent integration
pip install semantica[llm-litellm]          # OpenAI, Anthropic, Gemini, Mistral, Llama, Groq, Cohere, Bedrock, Ollama, DeepSeek, and more
pip install semantica[graph-neo4j]          # Neo4j graph store (LPG)
pip install semantica[graph-falkordb]       # FalkorDB graph store (LPG)
pip install semantica[graph-apache-age]     # Apache AGE graph store (LPG)
pip install semantica[graph-amazon-neptune] # AWS Neptune graph store (LPG)
pip install semantica[tripletstore-oxigraph] # Embedded in-memory/on-disk RDF store
# RDF triple stores (Blazegraph, Apache Jena, Eclipse RDF4J) need no extra:
# semantica.triplet_store talks SPARQL over HTTP using the core `requests` dependency
pip install semantica[vectorstore-qdrant]   # Qdrant vector store
pip install semantica[vectorstore-pinecone] # Pinecone vector store
pip install semantica[db-snowflake]         # Snowflake
pip install semantica[db-databricks]        # Databricks (SDK + SQL connector)
pip install semantica[ingest-parquet]       # Parquet / PyArrow
pip install semantica[ingest-arrow]        # Apache Arrow, Feather, IPC
pip install semantica[viz]                  # HTML interactive visualization
pip install semantica[watch]                # Directory file watcher
pip install semantica[explorer]             # Knowledge Explorer dashboard
For production deployments, use Docker or Kubernetes rather than a local pip install. Set SEMANTICA_SECRET_KEY, configure a persistent LPG graph store (Neo4j / FalkorDB / Apache AGE / AWS Neptune) and/or RDF triple store (Blazegraph / Apache Jena / Eclipse RDF4J), and point the vector store at a hosted backend (Qdrant / Pinecone). See ARCHITECTURE.md for the full deployment topology.
# From source
git clone https://github.com/semantica-agi/semantica.git
cd semantica && pip install -e ".[dev]" && pytest tests/
Enterprise
On-premises deployment · Private cloud · Custom domain implementations · SLA-backed support · Professional services for regulated industries (finance, healthcare, legal, government).
getsemantica.ai for enterprise solutions and pricing.
Community & Support
| Discord | discord.gg/sV34vps5hH: real-time help, showcases, and announcements |
| GitHub Discussions | Q&A and feature requests |
| GitHub Issues | Bug reports |
| Documentation | docs.getsemantica.ai |
| Cookbook | Runnable Jupyter notebooks |
| Changelog | CHANGELOG.md · Release Notes |
Star History
Contributors
Contributing
All contributions are welcome: bug fixes, features, tests, and documentation.
- Fork the repo and create a branch
pip install -e ".[dev]"- Write tests alongside your changes (
pytest tests/) - Open a PR and tag
@KaifAhmad1for review
See CONTRIBUTING.md for full guidelines.
Discover Repositories
Search across tracked repositories by name or description