NVIDIA/Personal-AI-Router
Router that virtually distributes inference across connected devices in the home.
Build with Backblaze B2
SDKs, agent skills, IDE extensions, and reference pipelines from Backblaze Labs. All open source.
Loading star history...
Where it stands
Rank, growth pace and release cadence relative to everything GStars tracks.
3 releases in the last 90 days, the latest 12 days ago, with 15 contributors on GitHub.
Use Cases & Benefits
- Distributes AI inference requests across multiple local devices on a home network to optimize workload and resource use.
- Enables local routing of AI inference without pooling GPU memory or sharding models, preserving data privacy within the network.
- Use for managing concurrent AI workloads in multi-agent applications across heterogeneous devices running different OSes.
- Use for setting up a local cluster of machines to run Ollama, LM Studio, or llama.cpp inference engines seamlessly.
- Use for developers needing a local proxy that supports OpenAI-compatible and Anthropic Messages API requests for AI model inference.
Should you depend on it?
License terms, project hygiene and risks, from GitHub metadata and GStars' snapshots.
License
Apache 2.0
Permissive: commercial use, modification and redistribution are allowed with attribution; includes an explicit patent grant from contributors.
Community files
- README: present
- Contributing guide: present
- Code of conduct: present
Watch-outs
No watch-outs from GStars' checks.
General guidance from repository metadata, not legal advice. How we score
From the README
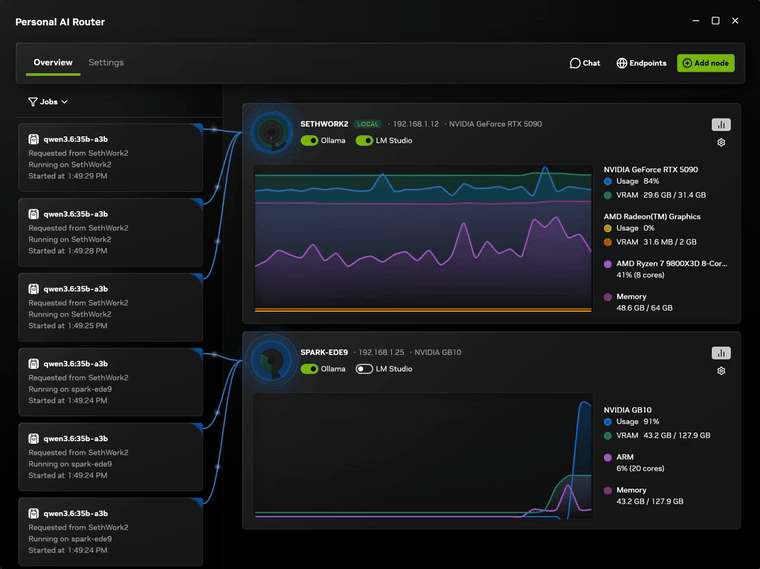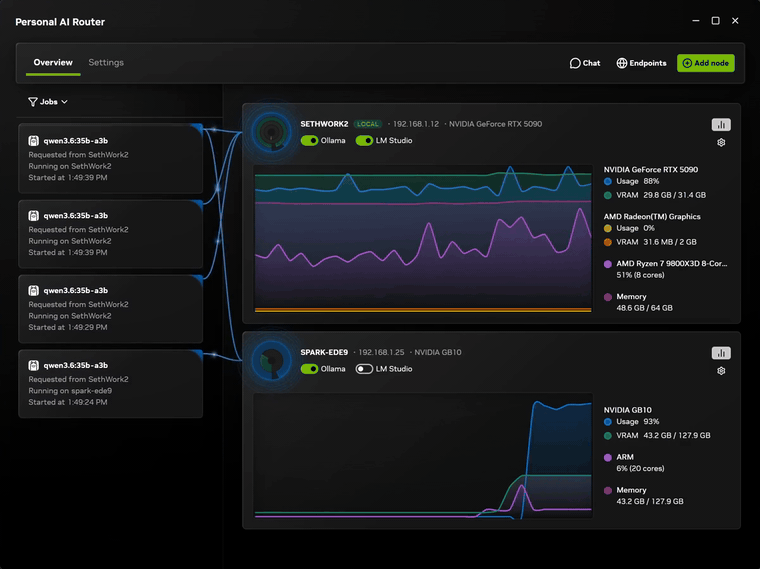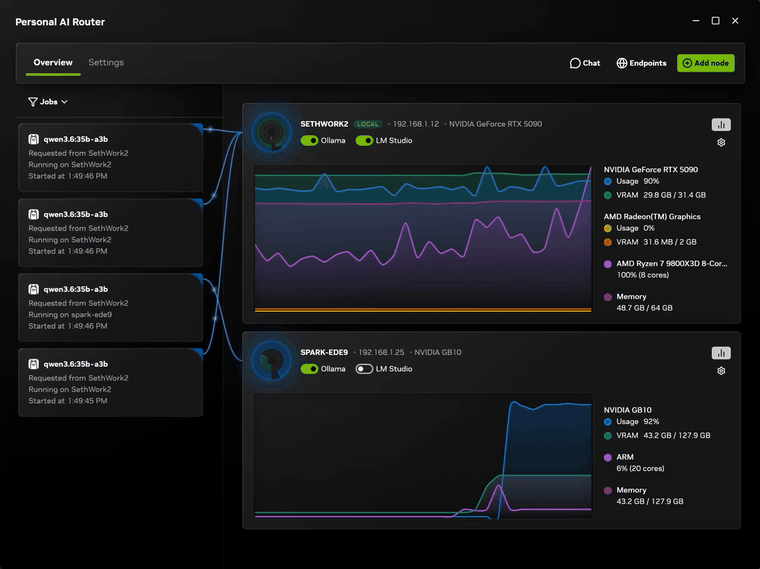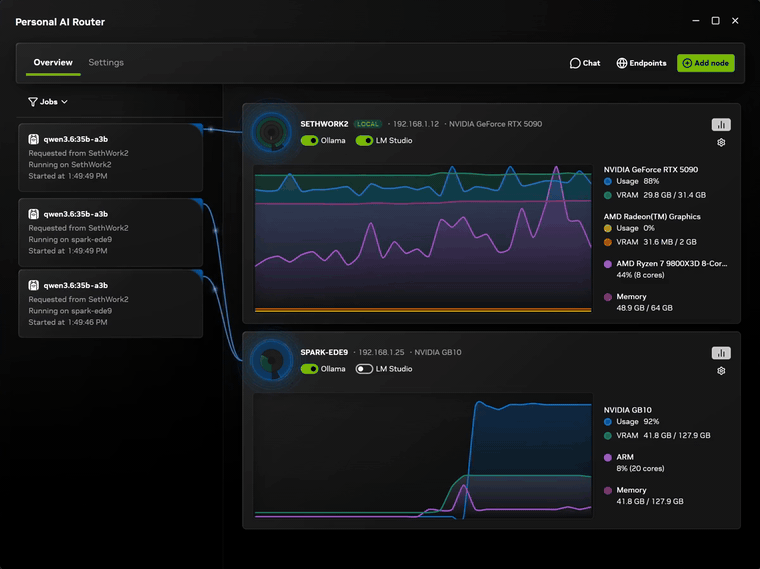
NVIDIA Personal AI Router (PAIR), shown as NVIDIA PAIR once installed, is a local inference router for a group of compatible computers on the same network. It discovers participating nodes, manages supported inference engines, and presents local proxy endpoints for Ollama-compatible, OpenAI-compatible, and Anthropic Messages API requests. Independent requests can be routed to eligible nodes according to engine availability, model availability, and current workload.
PAIR is useful for concurrent local workloads such as multi-agent applications. Prompts and responses are intended to remain on the local network when every configured client, model source, engine, and node is local.
PAIR routes each independent request to one node. It does not pool GPU memory, combine GPUs into a larger logical GPU, shard one model across machines, or split an in-flight inference request between nodes.
Two paired machines: requests arrive on one, run on whichever node suits each one, and both report live GPU and memory use throughout. Watch the full clip.
Daily snapshots
Stars gained per day, and how forks and open issues moved, from GStars' daily snapshots
+120 stars over 21 days across 4 snapshot days; best day +8 on Oct 7.
Forks
283+20
Open issues
85-12
Compared with peers in Backend
Fastest-growing repositories GStars tracks in this cohort for the week of Nov 1, by 7-day star growth
| Repository | Stars | +7d | Health | Last release |
|---|---|---|---|---|
| anthropics/skills | 187.8K | +2.9K | 15 | — |
| DuarteSantos8/openGym | 19.7K | +2.4K | 60 | 2 days ago |
| shiyu-coder/Kronos | 47.0K | +2.3K | 16 | — |
| NationalSecurityAgency/ghidra | 98.2K | +2.3K | 64 | 14 days ago |
| microsoft/VibeVoice | 56.0K | +1.1K | 29 | — |
| NVIDIA/Personal-AI-Router | 1.7K | — | 51 | 12 days ago |
| Category median | 56.0K | +2.3K | 29 | — |
Also by NVIDIA
Other repositories from this maintainer that GStars tracks
- Python24.5K stars
SkillSpector
Security scanner for AI agent skills. Detect vulnerabilities, malicious patterns, security risks, prompt injection, data exfiltration, and supply-chain risks in Claude Code, Codex, and MCP skills before you install them.
- TypeScript22.8K stars
NemoClaw
Run agents like Hermes, LangChain Deep Agents, and OpenClaw more securely inside NVIDIA OpenShell with managed inference
- Rust21.2K stars
OpenShell
OpenShell is the safe, private runtime for autonomous AI agents.
- Python18.3K stars
Megatron-LM
Ongoing research training transformer models at scale
- Python15.0K stars
TensorRT-LLM
TensorRT LLM provides users with an easy-to-use Python API to define Large Language Models (LLMs) and supports state-of-the-art optimizations to perform inference efficiently on NVIDIA GPUs. TensorRT LLM also contains components to create Python and C++ runtimes that orchestrate the inference execution in a performant way.
Discover Repositories
Search across tracked repositories by name or description